

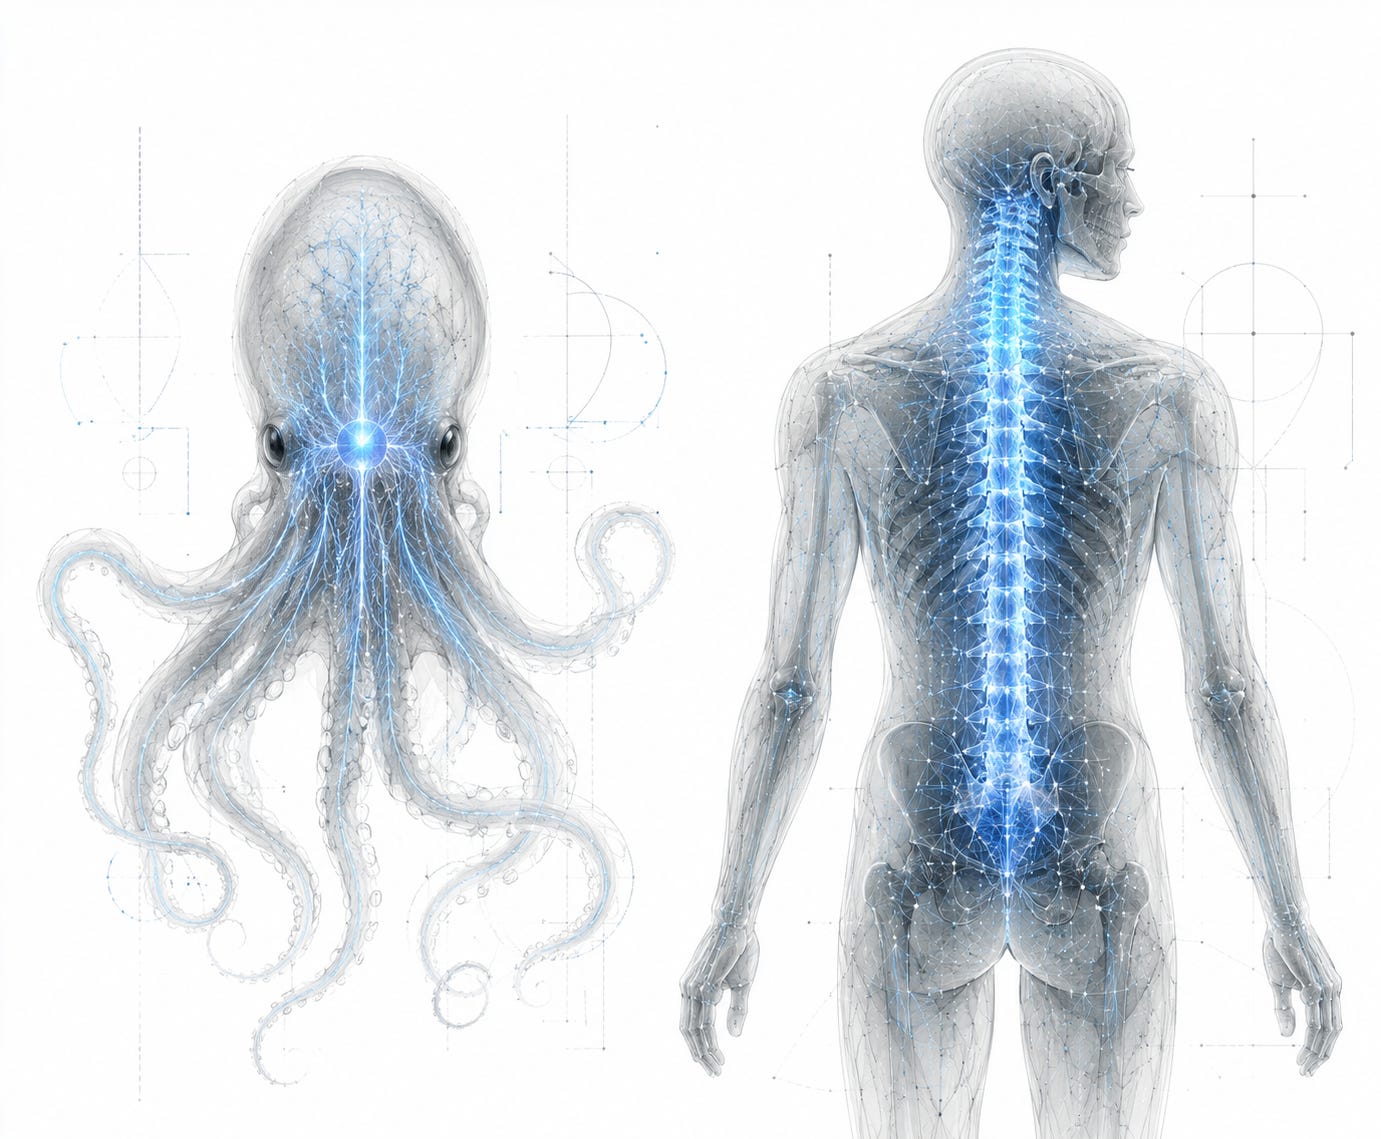
The Invertebrate Problem
Watch a modern AI agent in action. It receives a task, reasons about it, decides on a plan, executes steps, adjusts on the fly, and sometimes (often, actually) does something unpredictable that breaks the entire workflow.
This is the invertebrate architecture: the LLM is the brain, the body, and the spine all at once. It decides what to do, how to do it, and in what order. Every decision is probabilistic. Every execution is a fresh generation. The agent is flexible, capable of remarkable contortions but structurally unsound.
The numbers tell the story. Multi-agent success rates degrade from 58% on single-turn tasks to 35% on multi-turn ones. Nearly 79% of failures stem not from reasoning errors but from specification and coordination issues. The agent knows what to do. It just can’t reliably do it the same way twice.
Enterprises have noticed. While 88% of organisations now use AI in at least one function, roughly two-thirds still can’t scale beyond pilot projects. The gap isn’t intelligence. It’s structure.
More Tentacles Won’t Help
The current industry response to unreliable agents is to give them more tools. More MCP connectors. More skills. More context. An agent with 50 integrations can read your CRM, query your database, send emails, generate charts, and search the web : all in one turn.
But it still decides which tools to call, in what order, with what parameters, every single time. The workflow is emergent. The agent figures it out at runtime. More tools make a more capable invertebrate. Still an invertebrate.
This is the equivalent of giving an octopus more tentacles. The problem was never capability. It was structure.
Tools give the agent hands. What it’s missing is a spine : a rigid internal structure that says “you will do step A before step B, you will use this formula for X, you will not skip the validation check Y” regardless of which model is driving.
What Vertebrates Have That Invertebrates Don’t
In biology, the vertebrate innovation wasn’t a bigger brain. It was a spinal column : a rigid internal structure that constrains movement into reliable, repeatable patterns while freeing the nervous system to handle only what requires genuine intelligence.
An octopus is brilliant. It can open jars, solve puzzles, squeeze through impossible gaps. But you wouldn’t build a factory around one. You’d build it around vertebrates: organisms whose movements are predictable, repeatable, and structurally constrained, with intelligence deployed where it actually matters.
A vertebrate agent has:
A spine : deterministic, compiled workflow logic that defines what steps execute, in what order, with what constraints. This is code, not prompts. It runs the same way every time. It’s auditable, versionable, and testable.
Joints : bounded points where the LLM is invoked for genuine intelligence tasks: interpreting ambiguous text, drafting narrative, classifying edge cases. The LLM operates within a slot defined by the spine. It can move freely, but only within the range the joint allows.
Muscles : the domain knowledge, business rules, and validation logic that connect spine to action. An EBITDA margin is calculated as EBITDA / Revenue × 100. A compliance document must contain sections A, B, C in that order. These aren’t suggestions. They’re constraints encoded in code.
The LLM never decides the workflow’s path. It fills bounded slots within a structure it didn’t create and can’t override.
Graduated Determinism: Not All Vertebrae Are Equal
A real spine isn’t uniformly rigid. The cervical vertebrae allow the head to turn freely. The thoracic vertebrae lock the ribcage in place. The lumbar vertebrae bear load with controlled flexibility. The architecture should reflect this gradient.
Hard rules : the skull. Zero LLM involvement. EBITDA is calculated, not interpreted. The company logo goes bottom-right, 24px from the edge. A regulatory filing must contain these sections in this order. These are validators, layout constraints, calculation rules. If they fail, the output is rejected.
Soft rules : the thoracic spine. Deterministic defaults that humans can override. The executive summary is typically two slides. Financial projections default to three years historical plus two projected. The system proposes; the human disposes.
Bounded LLM slots : the joints. Runtime intelligence, contained. Given the financial data and the kick-off notes, write the narrative paragraph under the EBITDA bridge chart. Given the management bios, draft the key persons slide. The LLM fills a slot defined by the spine, never the other way around.
When semantic judgment is unavoidable, the pattern is what researchers call the “Safety Sandwich”: deterministic validation before the LLM call constrains the input; deterministic validation after the call constrains the output. The LLM is sandwiched between two layers of compiled rules. It can think freely within its slot. It cannot escape it.
This gradient, from fully deterministic to bounded probabilistic, is what makes vertebrate agents practical. Not every decision needs to be hard-coded. But every decision needs to know which category it belongs to.
Who Builds the Spine?
Here’s where the field reveals a gap.
The research demonstrates that vertebrate architecture works. Deterministic workflows with bounded LLM calls outperform autonomous agents on reliability, cost, and surprisingly on accuracy too. Models perform dramatically better when given curated structure than when they self-organize. One benchmark found a 16-pp improvement with curated skills, and zero or negative benefit from self-generated ones.
The models cannot build their own spine. Someone has to build it for them.
But who? Today, the answer is: a developer, manually, for each workflow. That’s where the node-based tools stop. It works for a handful of workflows. It doesn’t scale to the thousands of domain-specific processes an enterprise runs.
The missing piece is knowledge compilation : the systematic extraction of organisational knowledge (from documents, processes, expert minds, past deliverables) into the compiled, deterministic artifacts that form the spine. An ontology that structures what the organisation knows. Validation rules derived from how the organisation actually works. Bounded LLM slots placed exactly where genuine judgment is needed.
This compilation layer (not the models, not the raw knowledge) is where durable value accrues. The LLMs are commoditizing. The spines are not.
The Uncomfortable Implication
The dominant narrative in AI, that we need bigger, smarter, more autonomous agents, is directionally wrong for enterprise adoption.
What enterprises need isn’t more intelligence. It’s more structure around the intelligence they already have access to. The value isn’t in the model. It’s in the compilation layer that turns organisational knowledge into a reliable spine, then deploys any model’s intelligence within it.
The agent doesn’t need a bigger brain. It needs a spine.
Hadi Mahihenni is CEO and co-founder of Databold
We’re building the knowledge compilation layer for structured professional artifacts: the infrastructure that turns organisational expertise into reliable, auditable spines for AI-generated deliverables. We’ve validated the architecture on two live use cases (decision decks and financial data extraction workflows) and we’re raising to generalise it. If you’re an engineer who wants to work on this problem, or an investor who sees where it’s going, please reach out.
Notes & Further Reading
The empirical findings referenced in this piece draw from several recent research papers for those who want to go deeper:
[1] Multi-agent failure rates (79% from specification/coordination, 58%→35% degradation): Trooskens et al., “Compiled AI: Deterministic Code Generation for LLM-Based Workflow Automation,” April 2026. arxiv.org/abs/2604.05150
[2] The “Safety Sandwich” pattern and compile-time code generation achieving 57× cost reduction: same paper as [1].
[3] The “Blueprint First, Model Second” philosophy and Source Code Agent framework (+10.1pp over best baseline on τ-bench): Qiu et al., Alibaba Group, August 2025. arxiv.org/abs/2508.02721
[4] Curated skills = +16.2pp improvement, self-generated skills = zero or negative benefit, smaller models + good skills ≈ bigger models: Li et al., “SkillsBench,” February 2026. arxiv.org/abs/2602.12670
[5] Same compiled skill = up to 40% performance variance across models and frameworks: Chen et al., “SkVM,” April 2026 arxiv.org/abs/2604.03088; Ouyang et al., “SkCC,” May 2026 arxiv.org/abs/2605.03353.
[6] Multi-level skill compilation from agent trajectories (planning / functional / atomic): “SkillX,” submitted to ICML 2025. arxiv.org/abs/2604.04804
[7] The “Code Factory” paradigm — LLM writes code once, code runs forever: XY.AI Labs, “The Code Factory Manifesto,” January 2026. xy.ai/tech-behind-xyai/the-code-factory-manifesto
[8] Organisational tacit knowledge extraction via LLM-conducted expert interviews: Zuin et al., July 2025. arxiv.org/abs/2507.03811
[9] Codified expert domain knowledge achieving 206% improvement in AI agent output quality: “How to Build AI Agents by Augmenting LLMs with Codified Human Expert Domain Knowledge,” CAIN’26. arxiv.org/abs/2601.15153
[10] The “deterministic code as out
put layer” architecture applied to industrial operations: OSS Ventures, November 2024. medium.com/oss-ventures